This guide answers one question: how can a B1 learner shadow an English podcast that talks faster than the ear can follow? The short answer is to stop treating shadowing as a single pass. A fast episode is used three separate times, and each pass has one job: one pass for meaning, one pass with the transcript, and one pass for the mouth. The reader gets a repeatable routine built on a single short segment, a clear list of what to listen for, and a simple self check table. This task suits B1 learners who can already follow a slow, scripted lesson but lose words when a host speaks at a natural speed. It does not suit complete beginners, and it does not suit learners who have never worked with a transcript.
What This Task Solves
Fast English podcasts break the usual shadowing advice. A learner at B1 can repeat a slow lesson, but a natural host runs words together, drops sounds, and finishes a sentence before the learner finds the verb. The gap is not vocabulary. The gap is timing. This task closes that timing gap with one short episode and three separate passes. The goal is not to finish a whole series. The goal is to shadow sixty to ninety seconds of fast speech until the ear and the mouth agree.
The routine works because each pass has a single job. Mixing the passes, which most learners do, creates the familiar result: the learner reads the transcript while listening, understands nearly everything, and then still cannot shadow a single line. Separating the passes forces the ear to work without help on pass one, and forces the mouth to work on pass three.
The Three Sources That Keep the Task Honest
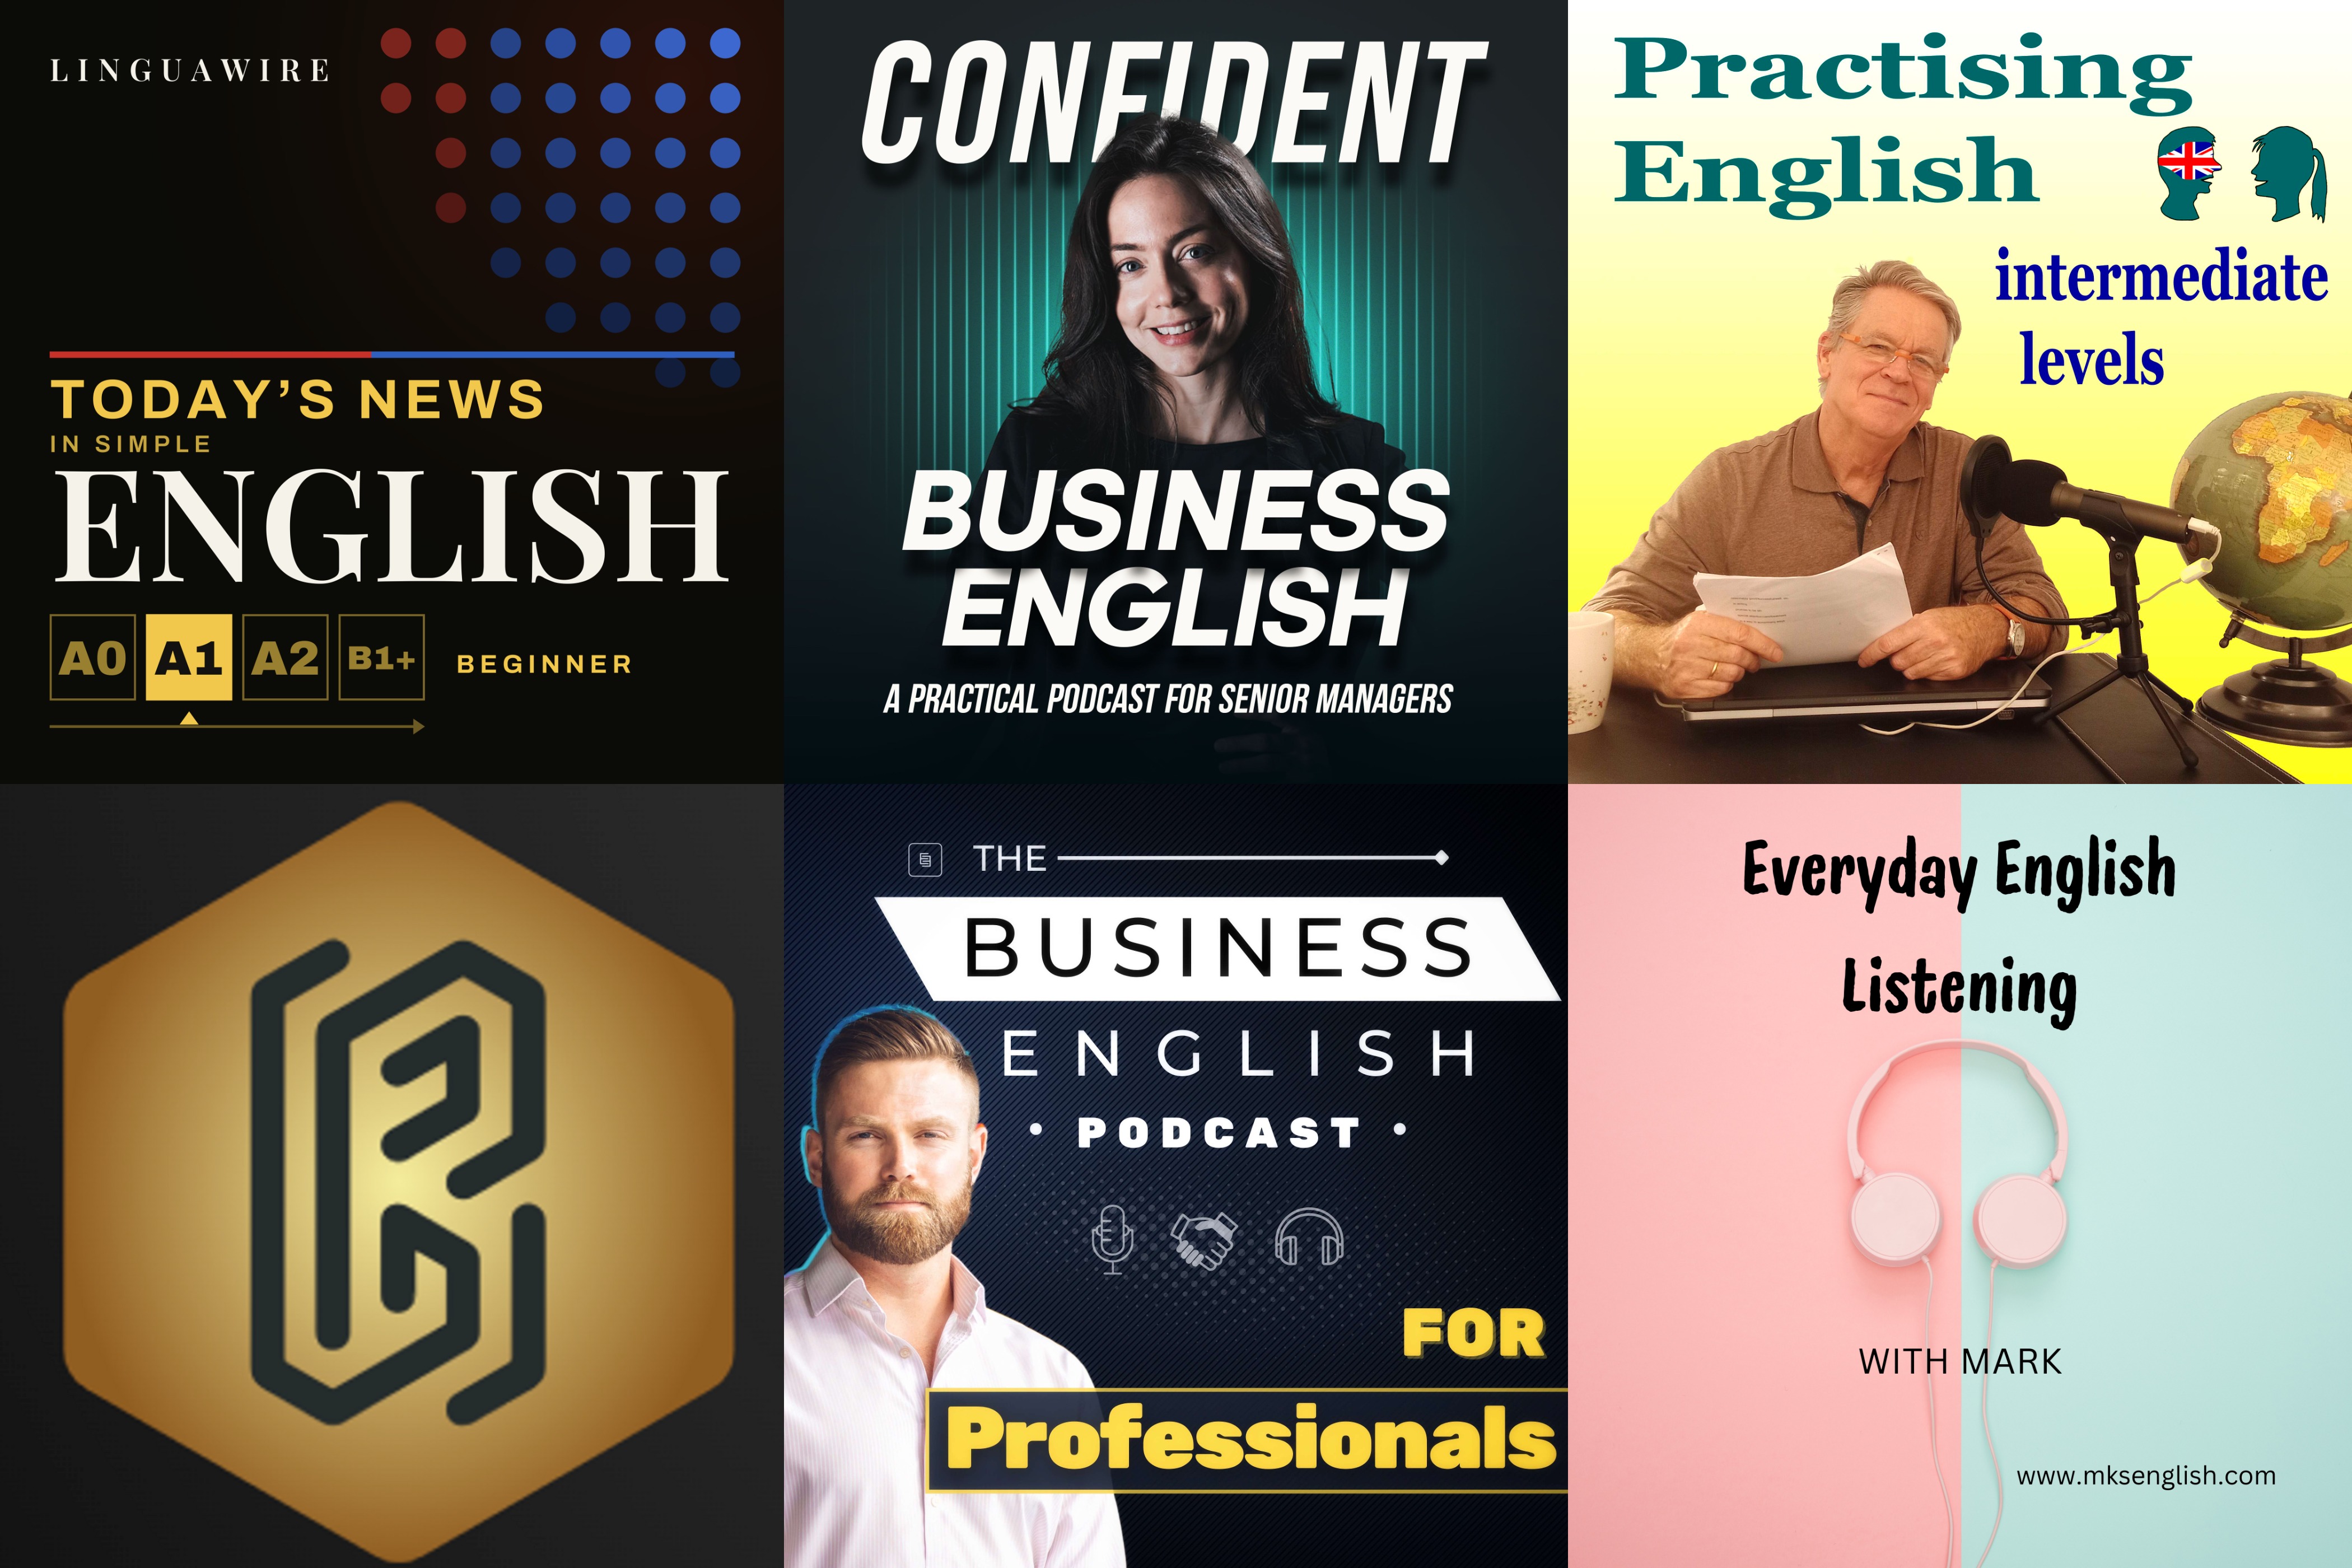
Part of shadowing well is choosing audio that can be checked. The examples below are chosen because each one publishes both audio and a transcript, so a learner can confirm what was actually said instead of guessing. None of these are presented as personal test results. They are publicly available shows with documented transcripts, and they cover three different speeds.
- BBC Learning English, "6 Minute English." About six minutes per episode, British accent, a paced studio conversation. A free transcript is published on the BBC Learning English site. This is the bridge source, faster than a learner lesson but still clear.
- BBC Learning English, "The English We Speak." About three minutes, British accent, one short phrase explained per episode. A transcript is published on the same site. This is the warm up source.
- NPR, "Up First." About twelve to fifteen minutes, American accent, a fast news conversation. A transcript is published on npr.org. This is the target source, close to the speed of natural speech.
A learner picks one bridge episode and one short segment of the target show. Only a segment is needed, roughly sixty to ninety seconds. Long is not better here. A clean segment that can be repeated five times beats twenty minutes played once.
Pass 1: Blind Listening
The first pass uses no text. The learner plays the sixty to ninety second segment once at normal speed and writes down only the main idea in one sentence. Not every word. One sentence.
Then the same segment plays a second time. This time the learner marks three moments where the audio seemed to blur. These are the blur points, and they are the real homework. A blur point is useful information. It shows exactly where connected speech beat the ear.
Nothing is repeated more than twice in pass one. More repeats turn listening into decoding, and decoding belongs to pass two.
Pass 2: Transcript Check
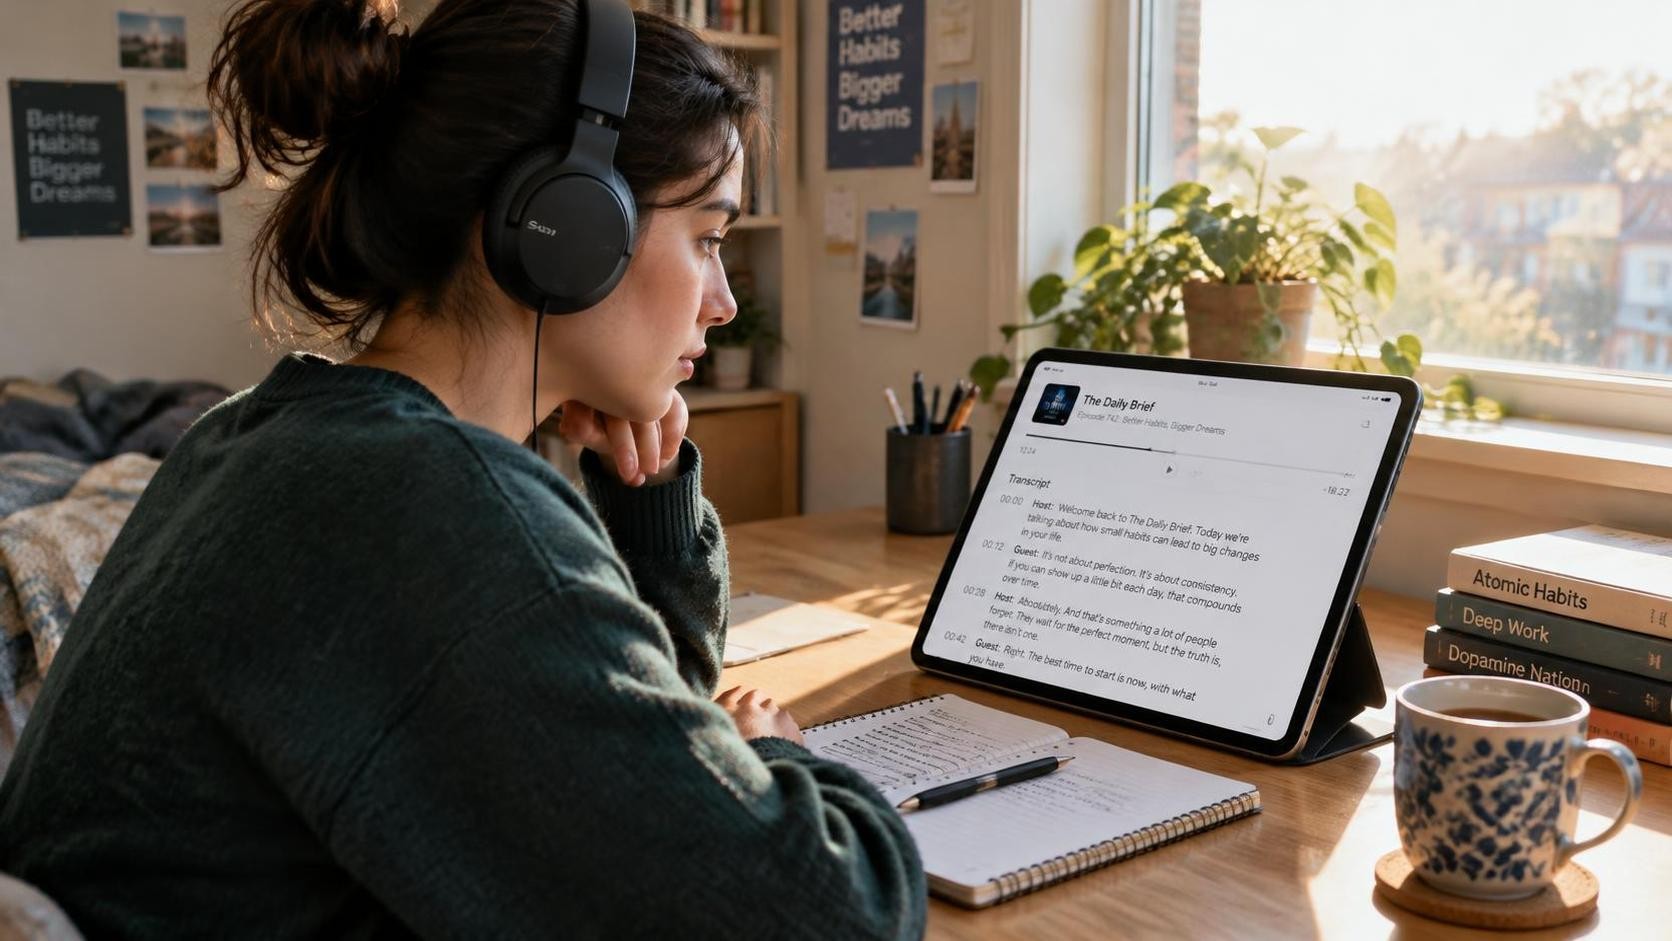
The second pass adds the transcript. The learner reads along while the audio plays, and checks the three blur points. In almost every case the missing words are ordinary words, not rare ones. The blur is created by how the words were joined, not by what they meant.
The learner then circles every place where the spoken form and the written form do not match. "Want to" is heard as "wanna." "Going to" is heard as "gonna." A final "t" disappears before a consonant. These circles become the practice list for pass three.
This is also where meaning is confirmed. If a line still makes no sense after reading, the learner looks up the phrase, writes a short note, and moves on. The target is understanding, not translation.
Pass 3: Shadowing
The third pass is the practice pass. The learner plays a single sentence, pauses, and repeats it out loud, copying the rhythm rather than the spelling. Then the learner plays the sentence again and speaks at the same time as the host, like a shadow.
Two rules keep this pass honest.
- Slow the audio only if the blur is still total. Normal speed is the goal, but a setting around three quarters speed is allowed for one or two lines, then removed.
- Copy timing before copying sounds. A learner who matches the rhythm but mispronounces one vowel is closer to the target than a learner who says every sound slowly and evenly.
After the single sentences, the learner runs the full segment at normal speed three times, speaking along each time. The mouth will drift behind the audio at first. That drift shrinking is the point of the whole exercise.
Short Final Step: Retell in Own Words
The learner stops the audio and retells the segment out loud in three or four sentences, without the transcript. This step shows that the segment was understood rather than echoed. A retell that keeps the meaning but changes the words is a success. A retell that repeats the host word for word usually means the audio was memorized instead of processed.
Three Sound Features to Watch in Fast Speech
Most blur points come from a small set of habits. Watching for these three habits turns a vague difficulty into a short, fixable list.
1. Linking
Words are joined so that a final consonant slides into the next vowel. In "an apple," the sound runs together as one unit. In "turn it off," the /n/ and the /t/ and the /t/ attach across the word gaps. A learner who expects clean pauses between words will hear one long blur where the speaker produced three short words.
2. Weak Forms and the Schwa
Function words shrink in fast speech. "For" becomes a short /fə/, "to" becomes /tə/, and "and" becomes /ən/. The stressed words carry the meaning, and the weak words almost vanish. A learner who listens for every full vowel will keep missing the small words, even when the big words are clear.
3. Elision and Disappearing Sounds
Some sounds are dropped entirely when they sit between other consonants. In "next day," the /t/ can disappear. In "best friend," the /t/ can soften. This is not sloppy speech. It is normal English, and it is the reason a transcript check is so useful: the dropped sound is still written on the page.
Self-Assessment Table
| What to check | Strong yes | Needs another pass |
|---|---|---|
| Main idea of the segment in one sentence | written without the transcript | only clear after reading |
| Three blur points | found and named | not noticed |
| Spoken versus written mismatches | five or more circled | none circled |
| Shadowing at normal speed | mouth stays with the audio | mouth falls behind |
| Retell in own words | meaning kept, words changed | words memorized |
One Tool That Fits This Routine
A learner who wants to slow a fast segment, loop a single line, and compare a recording side by side can use a tool built for that job. ListenLeap is one example. It plays podcasts and video with adjustable speed, line by line transcripts, and short repeat exercises, so the three passes above can happen in one place instead of three. It suits a learner who already follows this routine and wants the audio handled cleanly. It does not replace the routine, and it is not needed by a learner who is happy with a free podcast app and a printed transcript. A learner who has not yet built the habit of blind listening should fix that first, because no tool makes pass one easier.
Putting the Routine to Work
The whole routine fits into about twenty minutes, and it is repeated on the same segment once a day for a few days before the learner moves to a new one. The same segment is not boring after three days. It becomes familiar, and familiarity is what allows the mouth to catch the audio. A learner who changes the segment every day never gets the repetition that shadowing needs.
Progress shows up in a specific way. The blur points from pass one shrink from many to few. The mismatches circled in pass two become shorter. And in pass three, the moment when the mouth drifts behind the audio arrives later each week. When a fast podcast stops sounding like a wall of sound and starts sounding like words, the method has done its job.
Start with one bridge episode at a comfortable speed. Move to the faster source only when the bridge segment can be shadowed at normal speed without pausing. Speed is earned in small steps, not jumped to in one day.
Comments
No comments yet.
Leave a Comment